Interactive map
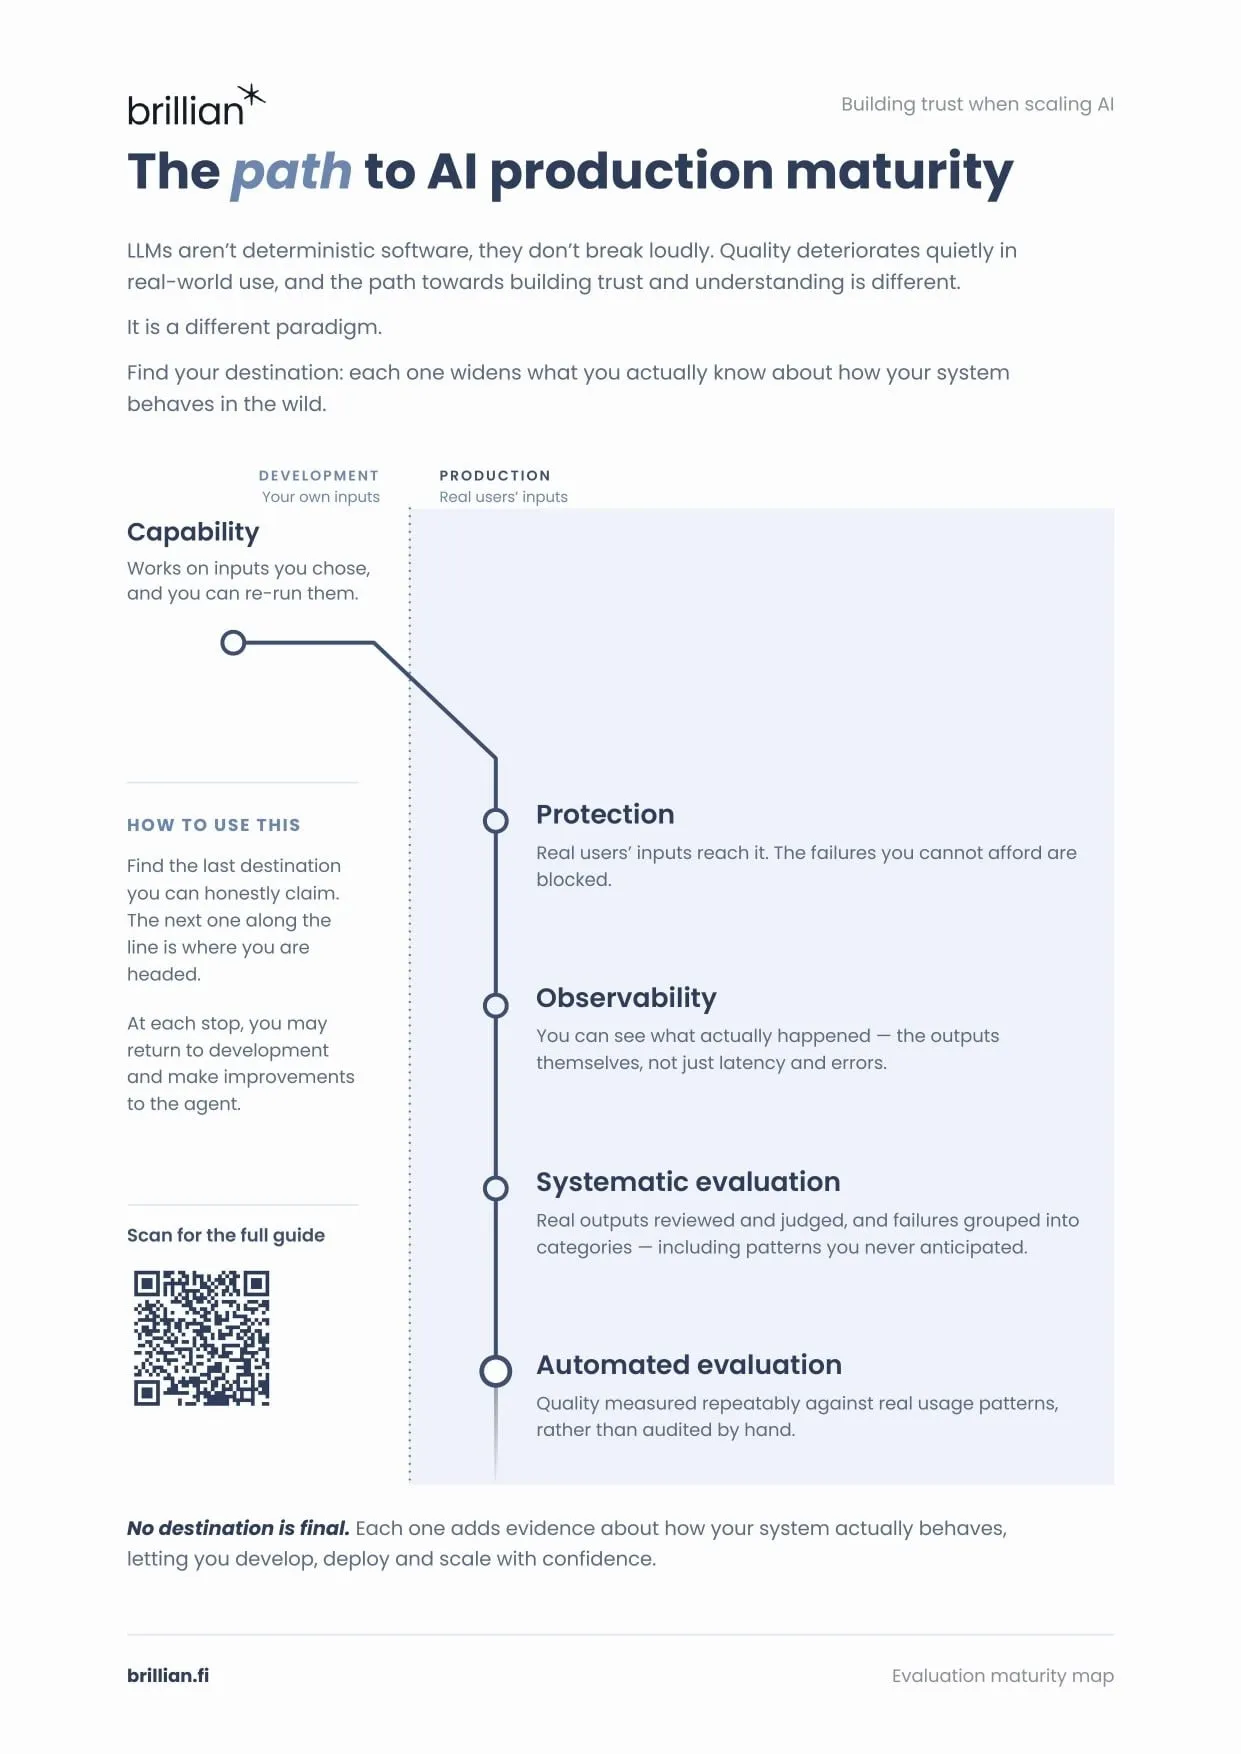
The path to AI production maturity
This map is for anyone about to put an LLM system into production, or already running one.
LLMs aren't deterministic software, they don't break loudly. Quality deteriorates quietly in real-world use, and the path towards building trust and understanding is different. It is a different paradigm.
Tap a stop on the map to see what it means.
Capability
- You can answer
- Does it work on the cases you chose?
- You still can’t answer
- Anything about the inputs you didn’t think of.
Protection
- What it is
- Deterministic checks, always on, cheap. They block the failures you can’t afford.
- You still can’t answer
- What the outputs that do get through are actually like.
Provides basic safety so you can focus on exploring what real users do.
Observability
- What to record
- Inputs, outputs, and the process in between, not just latency and error rates.
- You still can’t answer
- Whether any of it was good.
Logging is not observability. It is a structured collection of everything that happens during a user interaction.
Systematic evaluation
- How it works
- You judge real outputs one at a time and record why each one is good or bad. Working through examples is how you build an understanding of how your system should behave, and what your product should be.
- You still can’t answer
- Whether a change improves things, without redoing the manual work.
Good can’t be defined in the abstract, only exemplified.
Automated evaluation
- The fork
- Matchable output can become a benchmark. Qualitative output more usefully becomes a rubric for a judge. Neither is the default.
- Either way
- The labelling is the prerequisite for both, the rubric has to come from somewhere.
No stop is final: what you learn flows back into the agent and its guardrails.
Where are you?
Find the last stop you can honestly claim. The next one along the line is your next investment, usually smaller than you think.
Want to talk through where you land?